
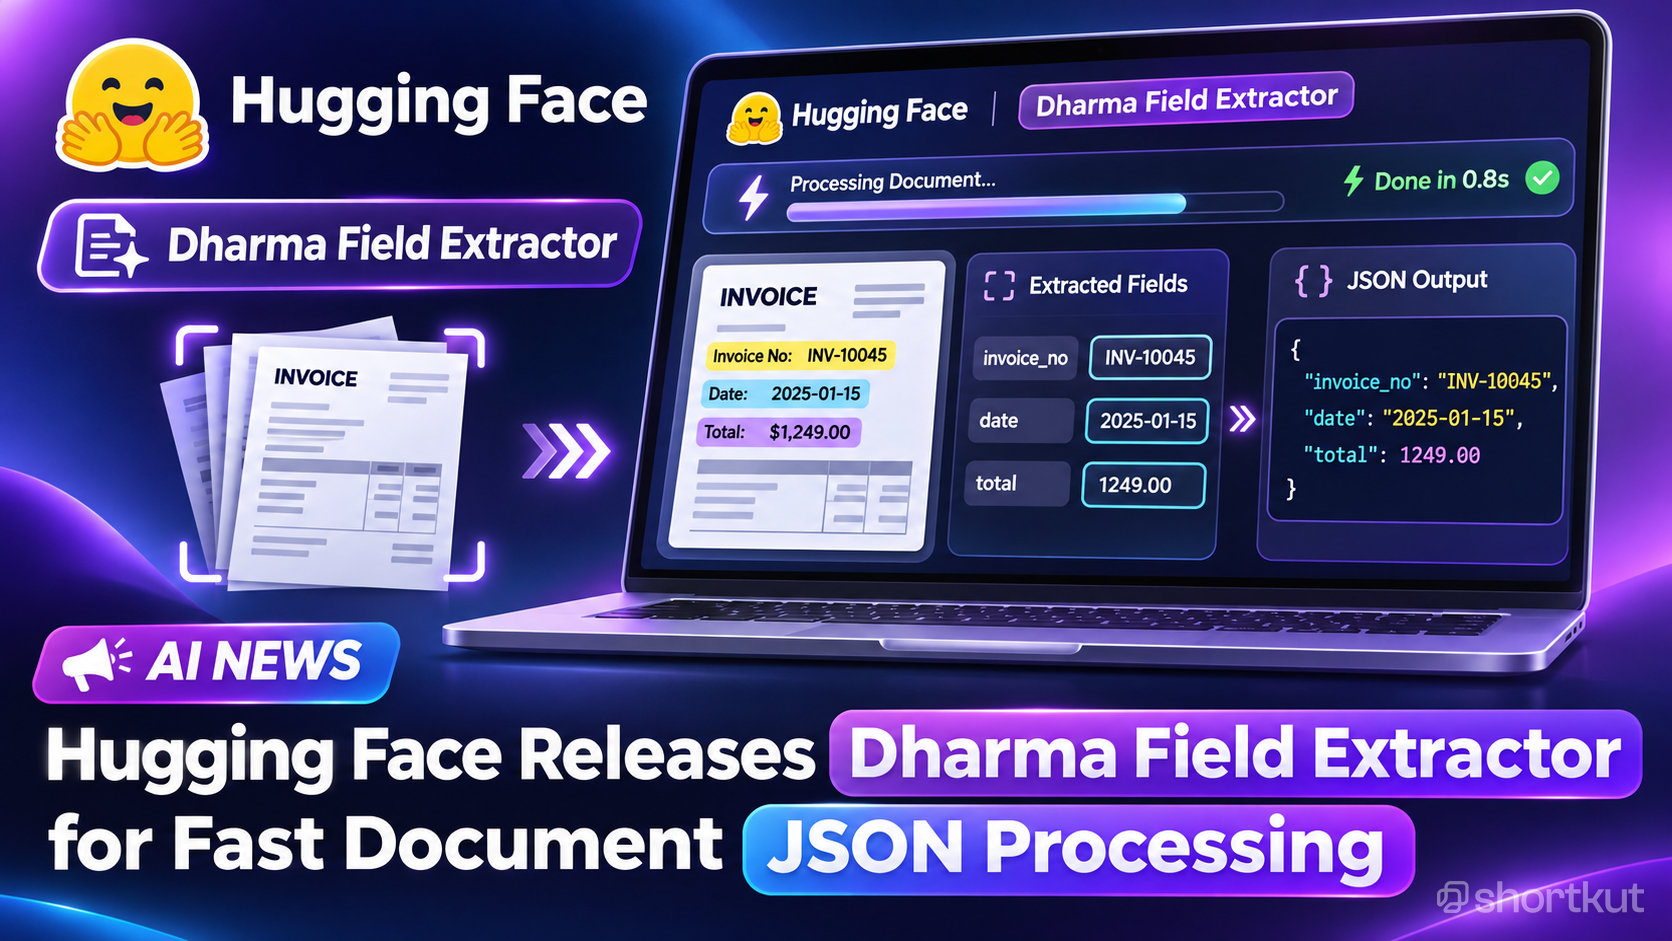
Hugging Face introduced Dharma Field Extractor to pull specific key data directly from documents into structured JSON format. Built on top of the 2 billion parameter DharmaOCR LITE v1.1 base model, it was trained using a LoRA adapter on 43,384 multi domain document examples including invoices, bank statements, IDs, and forms.
The model offers two extraction methods. Open mode scans documents to identify labels, values, and tables automatically without a preset list. Schema directed mode extracts exact user specified key names and data types, returning null when requested fields are missing rather than inventing false values.
Why it matters
Converting invoices, receipts, and forms into readable database entries usually requires high API costs or extra programming steps. A compact, specialized model allows developers, creators, and businesses to process high volumes of visual documents accurately using self hosted GPU infrastructure.
Try it yourself
Use this prompt with a visual AI model to extract key document fields directly into a JSON structure.
You are a document extraction assistant. Analyze this document: [paste document text or upload document image]. Extract the following target fields: [list desired keys, e.g. provider_name, document_date, total_price]. Output only a valid JSON object matching those exact key names. If a requested field is not present in the source material, assign its value as null.
Comments